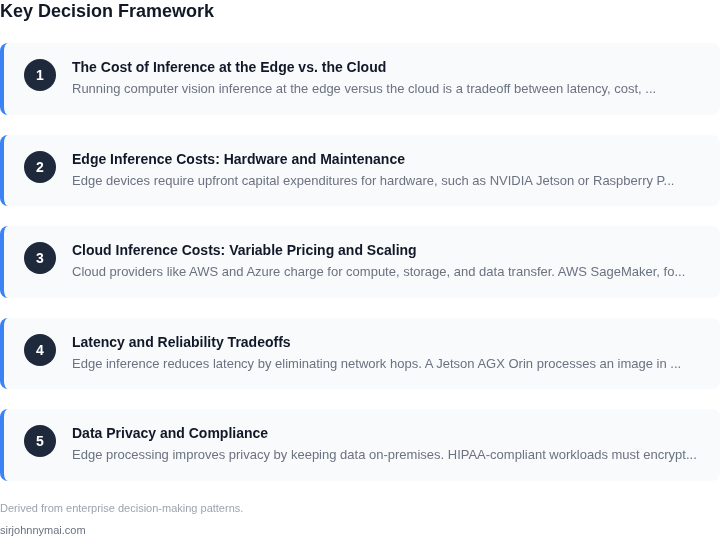
01. The Cost of Inference at the Edge vs. the Cloud
Running computer vision inference at the edge versus the cloud is a tradeoff between latency, cost, and reliability. Edge deployment reduces latency by processing data locally, but it increases costs due to hardware procurement, maintenance, and energy consumption. Cloud inference simplifies operations but introduces latency from network hops and variable pricing. The real cost depends on workload characteristics, data volume, and infrastructure constraints.
02. Edge Inference Costs: Hardware and Maintenance
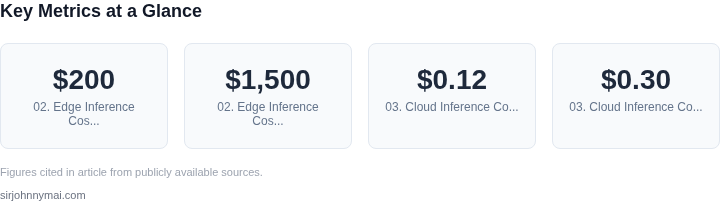
Edge devices require upfront capital expenditures for hardware, such as NVIDIA Jetson or Raspberry Pi boards, which can cost $200-$1,500 per unit. Consider a team of 8 engineers deploying 100 devices at $500 each: the total hardware cost is $50,000. Maintenance adds ongoing expenses for power, cooling, and software updates. At $100/month per device, the annual maintenance cost is $96,000. Energy consumption is another factor: a Jetson AGX Orin consumes 150W under load, costing $150/year at $0.15/kWh.
Scaling edge deployments is expensive. Each additional device requires provisioning, configuration, and troubleshooting. A single engineer can manage 20 devices; scaling to 100 devices requires hiring or outsourcing support. The cost of edge management tools, such as AWS IoT Greengrass or Balena, ranges from $50-$200/month per device. For 100 devices, this adds $5,000-$20,000 annually.
03. Cloud Inference Costs: Variable Pricing and Scaling
Cloud providers like AWS and Azure charge for compute, storage, and data transfer. AWS SageMaker, for example, costs $0.12-$0.30 per inference hour for GPU instances. A computer vision model processing 10,000 images per hour at $0.20 per hour costs $2,400/month. Data transfer adds $0.09/GB, so transferring 1TB of images costs $90.
Cloud costs are unpredictable due to variable pricing and burstable workloads. A model with occasional traffic spikes may see costs double during peak usage. AWS Lambda, for example, charges $0.20 per million requests, plus $1.60 per GB-second of compute time. A model with 5 million requests and 100GB-seconds of compute costs $1,600/month.
04. Latency and Reliability Tradeoffs
Edge inference reduces latency by eliminating network hops. A Jetson AGX Orin processes an image in 50ms, while a cloud API may take 100-500ms due to network and queueing delays. For real-time applications like autonomous vehicles, edge processing is critical. However, edge devices lack redundancy: a single failure can disrupt operations.
Cloud inference offers high availability but introduces latency. AWS Global Accelerator reduces latency to 50ms for global workloads, but this requires deploying in multiple regions. A single-region deployment may have 99.9% uptime, but multi-region deployments cost 3x more. For a model with 10,000 requests/hour, a single-region deployment costs $1,200/month, while a multi-region deployment costs $3,600/month.
05. Data Privacy and Compliance
Edge processing improves privacy by keeping data on-premises. HIPAA-compliant workloads must encrypt data at rest and in transit, adding $500-$2,000/month for compliance tools. Cloud providers like Azure offer HIPAA-compliant regions, but data egress fees apply. Transferring 1TB of medical images to a compliant region costs $180.
Edge deployments may violate compliance if data is stored or processed in non-compliant regions. For example, processing data in AWS us-east-1 (N. Virginia) is compliant, but us-west-2 (Oregon) may not meet all regulations. The cost of compliance audits and remediation can exceed $50,000 for large deployments.
Decision Framework
| Factor | Edge | Cloud |
|---|---|---|
| Latency | Low (local processing) | Variable (network-dependent) |
| Cost | High (hardware + maintenance) | Variable (pay-per-use) |
| Reliability | Low (single point of failure) | High (multi-region deployments) |
| Compliance | High (on-premises control) | Variable (region-dependent) |
Next Step
Pull your last 90 days of AWS SageMaker and IoT Greengrass usage data and calculate the total cost of edge vs. cloud inference. Compare the actual costs against your latency and reliability requirements. If edge costs exceed cloud costs by more than 20%, reassess your deployment strategy.
Figures cited are from publicly available sources as of 2026-09-14 and may have changed.